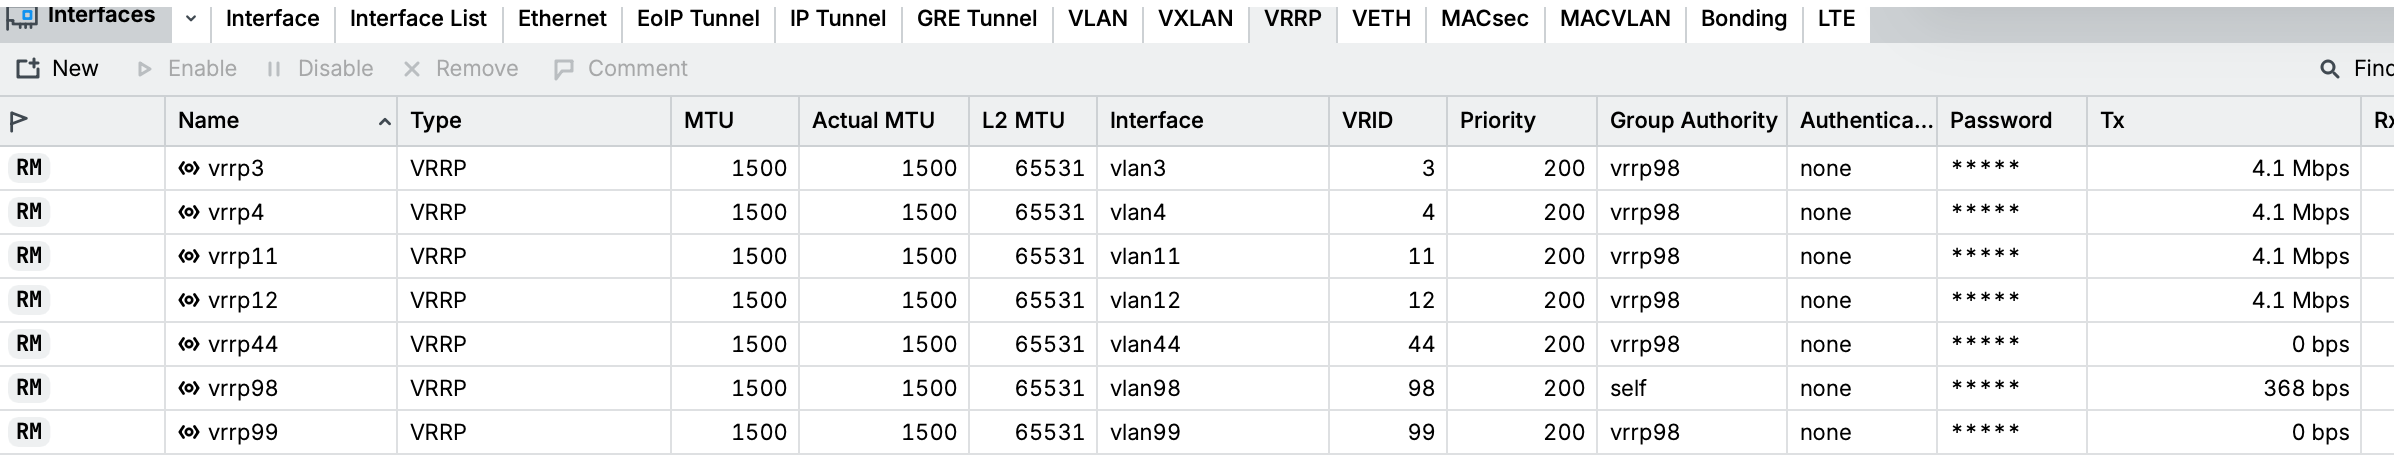
VRRP is driving me nuts for a few weeks now and it does something that should never, ever happen: "Randomly" my entire network goes down and by this I really mean it: All VLANs, no matter if part of a VRRP or not stop working and even traffic from two unrelated hosts in an unrelated VLAN stops working.
I have Router2 which is configured as master:
/interface vrrp
add group-authority=vrrp98 interface=vlan3 name=vrrp3 on-backup="/ip/dhcp-server/disable dhcp-lan" on-master="/ip/dhcp-server/enable dhcp-lan" priority=200 vrid=3
add group-authority=vrrp98 interface=vlan4 name=vrrp4 priority=200 vrid=4
add group-authority=vrrp98 interface=vlan11 name=vrrp11 on-backup="/ip/dhcp-server/disable dhcp-dev" on-master="/ip/dhcp-server/enable dhcp-dev" priority=200 vrid=11
add group-authority=vrrp98 interface=vlan12 name=vrrp12 on-backup="/ip/dhcp-server/enable dhcp-devp" on-master="/ip/dhcp-server/enable dhcp-devp" priority=200 vrid=12
add group-authority=vrrp98 interface=vlan44 name=vrrp44 priority=200 vrid=44
add group-authority=self interface=vlan98 name=vrrp98 priority=200 remote-address=10.227.2.1 sync-connection-tracking=yes vrid=98
add group-authority=vrrp98 interface=vlan99 name=vrrp99 on-backup="/ip/dhcp-server/disable dhcp-adm" on-master="/ip/dhcp-server/enable dhcp-adm" priority=200 vrid=99
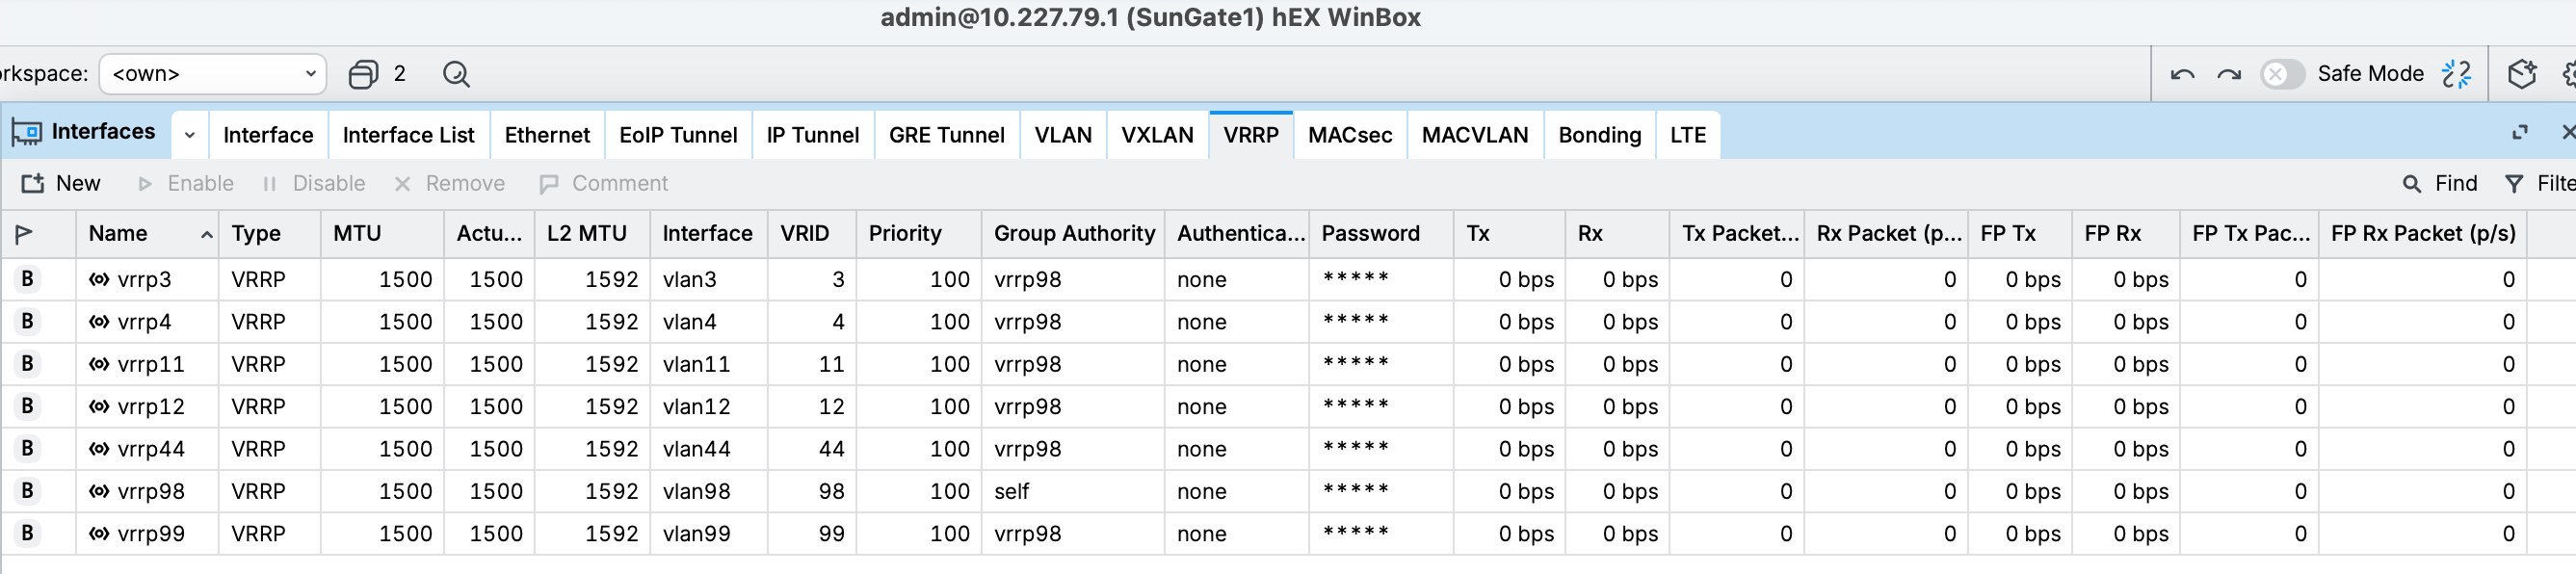
Then I have Router1 which is configured as slave:
/interface vrrp
add disabled=yes group-authority=vrrp98 interface=vlan3 name=vrrp3 on-backup="/ip/dhcp-server/disable dhcp-lan" on-master="/ip/dhcp-server/enable dhcp-lan" vrid=3
add group-authority=vrrp98 interface=vlan4 name=vrrp4 vrid=4
add group-authority=vrrp98 interface=vlan11 name=vrrp11 on-backup="/ip/dhcp-server/disable dhcp-dev" on-master="/ip/dhcp-server/enable dhcp-dev" vrid=11
add group-authority=vrrp98 interface=vlan12 name=vrrp12 on-backup="/ip/dhcp-server/enable dhcp-devp" on-master="/ip/dhcp-server/enable dhcp-devp" vrid=12
add group-authority=vrrp98 interface=vlan44 name=vrrp44 vrid=44
add group-authority=self interface=vlan98 name=vrrp98 remote-address=10.227.2.2 sync-connection-tracking=yes vrid=98
add group-authority=vrrp98 interface=vlan99 name=vrrp99 on-backup="/ip/dhcp-server/disable dhcp-adm" on-master="/ip/dhcp-server/enable dhcp-adm" vrid=99
All my interfaces are part of a VRF. As very well known, it's impossible to touch anything VRF related on RouterOS without finding a bug: A new bug I found is that connection sync seems to communicate via main VRF (*). For this reason alone, I added an additional interface vlan98 (along with vrrp98) on each router which is not assigned to any VRF. It acts as group-authority. The other interfaces are all using vrrp98 as group authority. Both routers can feely communicate via vlan98 (10.227.2.1 and 10.227.2.2).
The config as above has now been working for over an hour. Please note that vrrp3 on the slave is disabled.
Now comes the issue: once I enable it, all hell breaks loose. All VLANs, even the ones completely unrelated to vlan3 stop working. The only way to recover is to physically unplug router1 (then disable all VRRPs on router2, then plug back in router1, disable all VRRPs there and then re-enable them on router2).
This is the screenshot of a MacOS client connected to vlan3, pinging router1 (10.227.79.1), router2 (10.227.79.2) and internet (8.8.8.8) at the time the issue occurs:
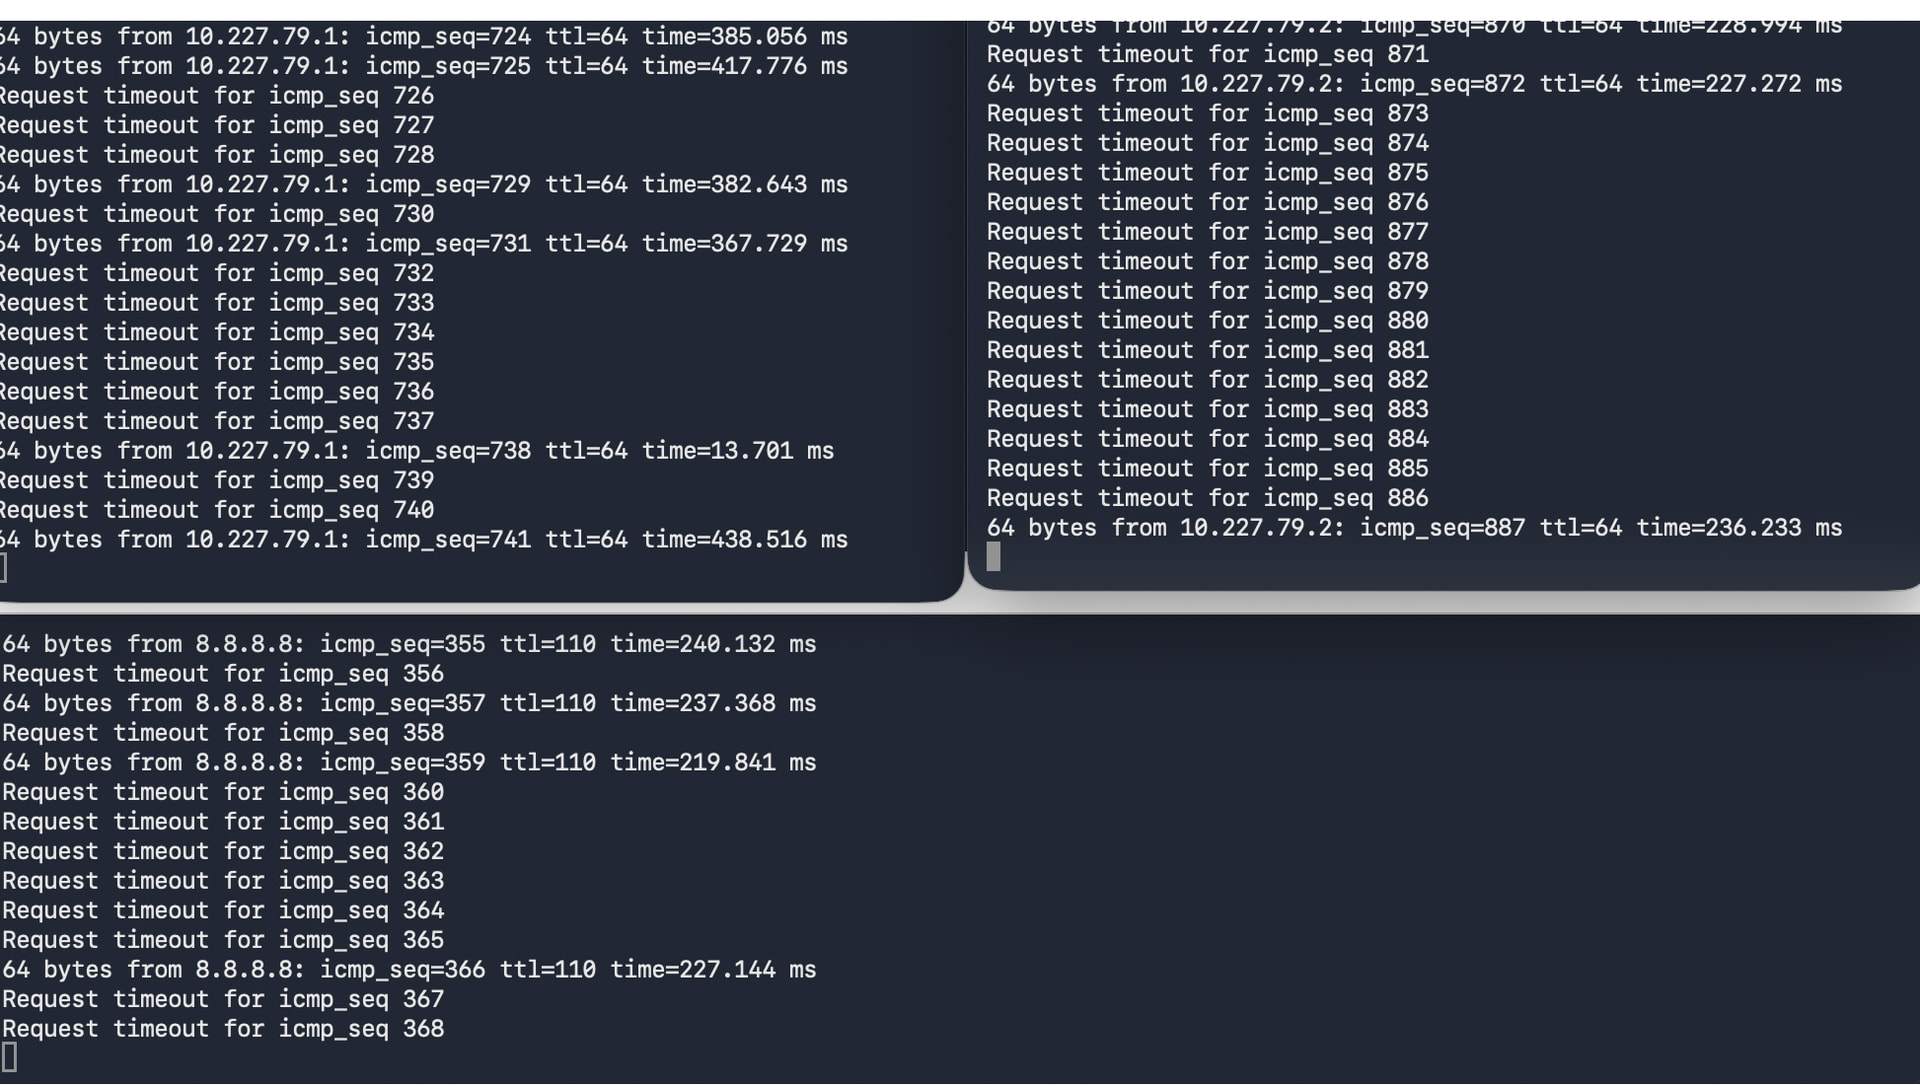
Hosts remain somewhat reachable but most of the packets are lost and if they respond, the response times are hundreds of milliseconds. Accessing either router via Winbox or SSH hangs forever and eventually times out.
For comparison, this is before I enabled vrrp3 and everything is working:
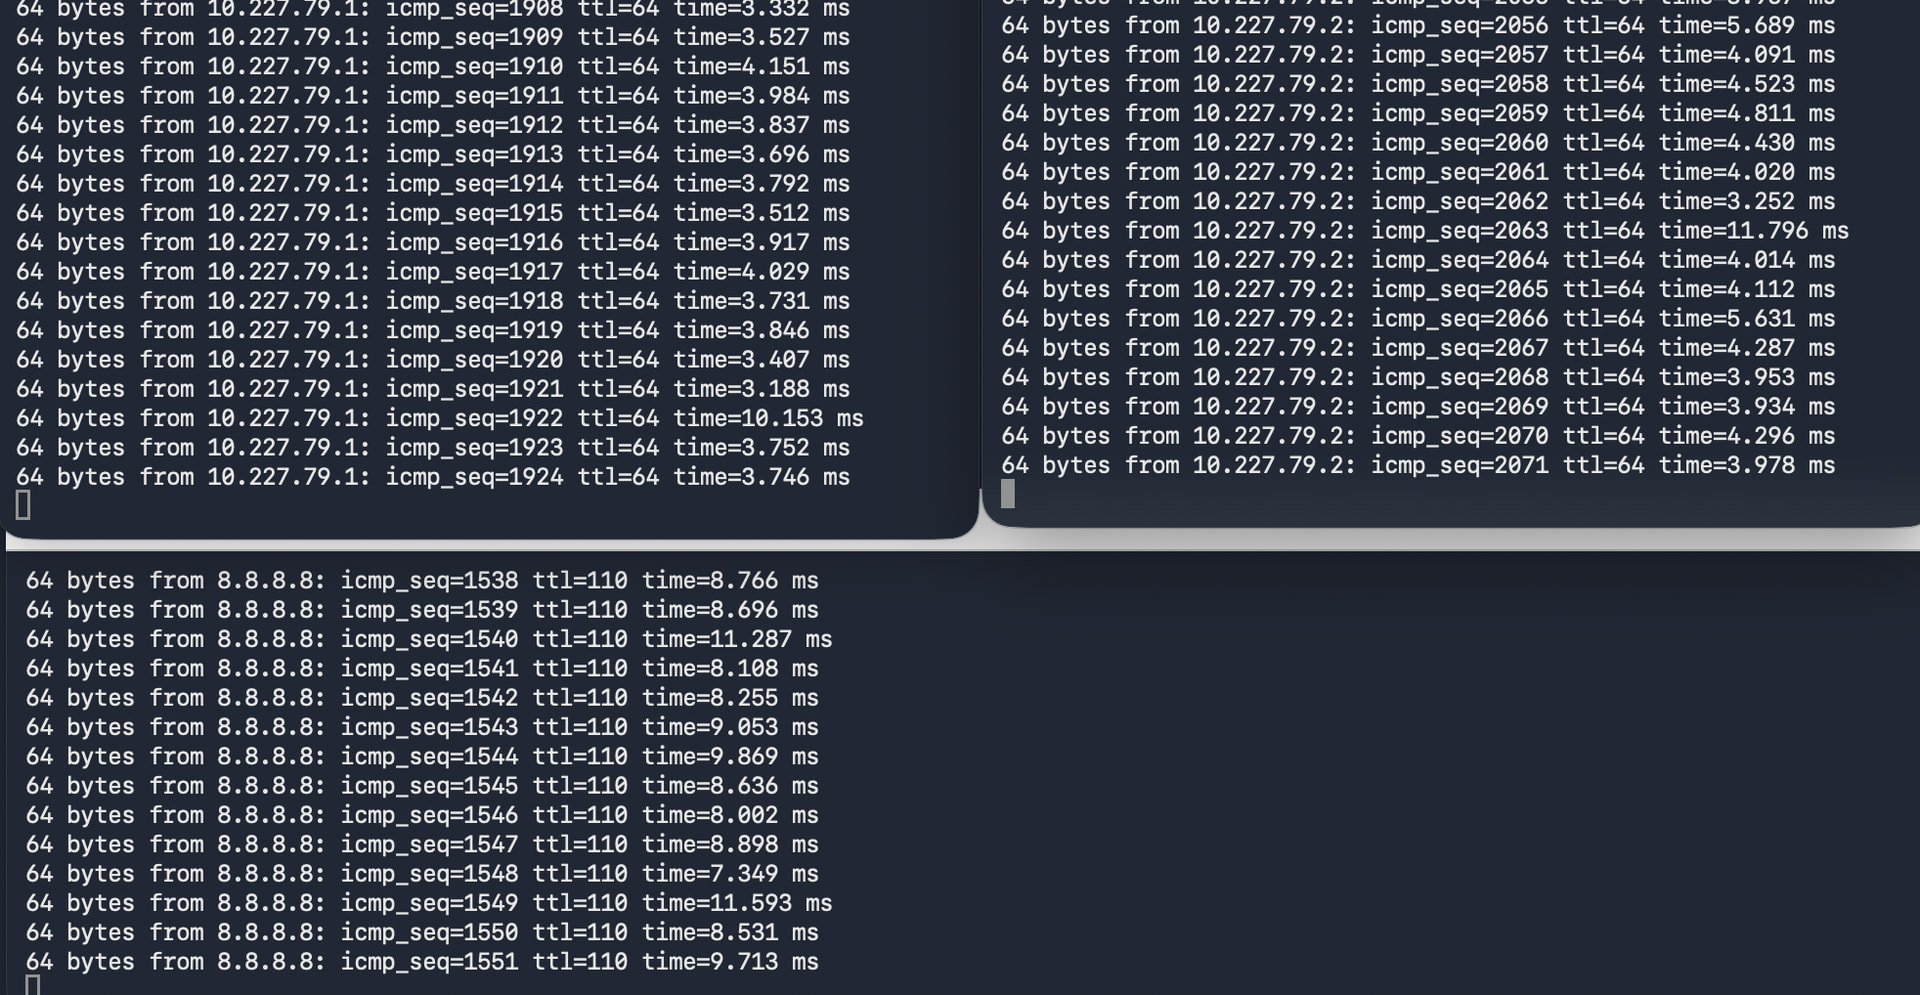
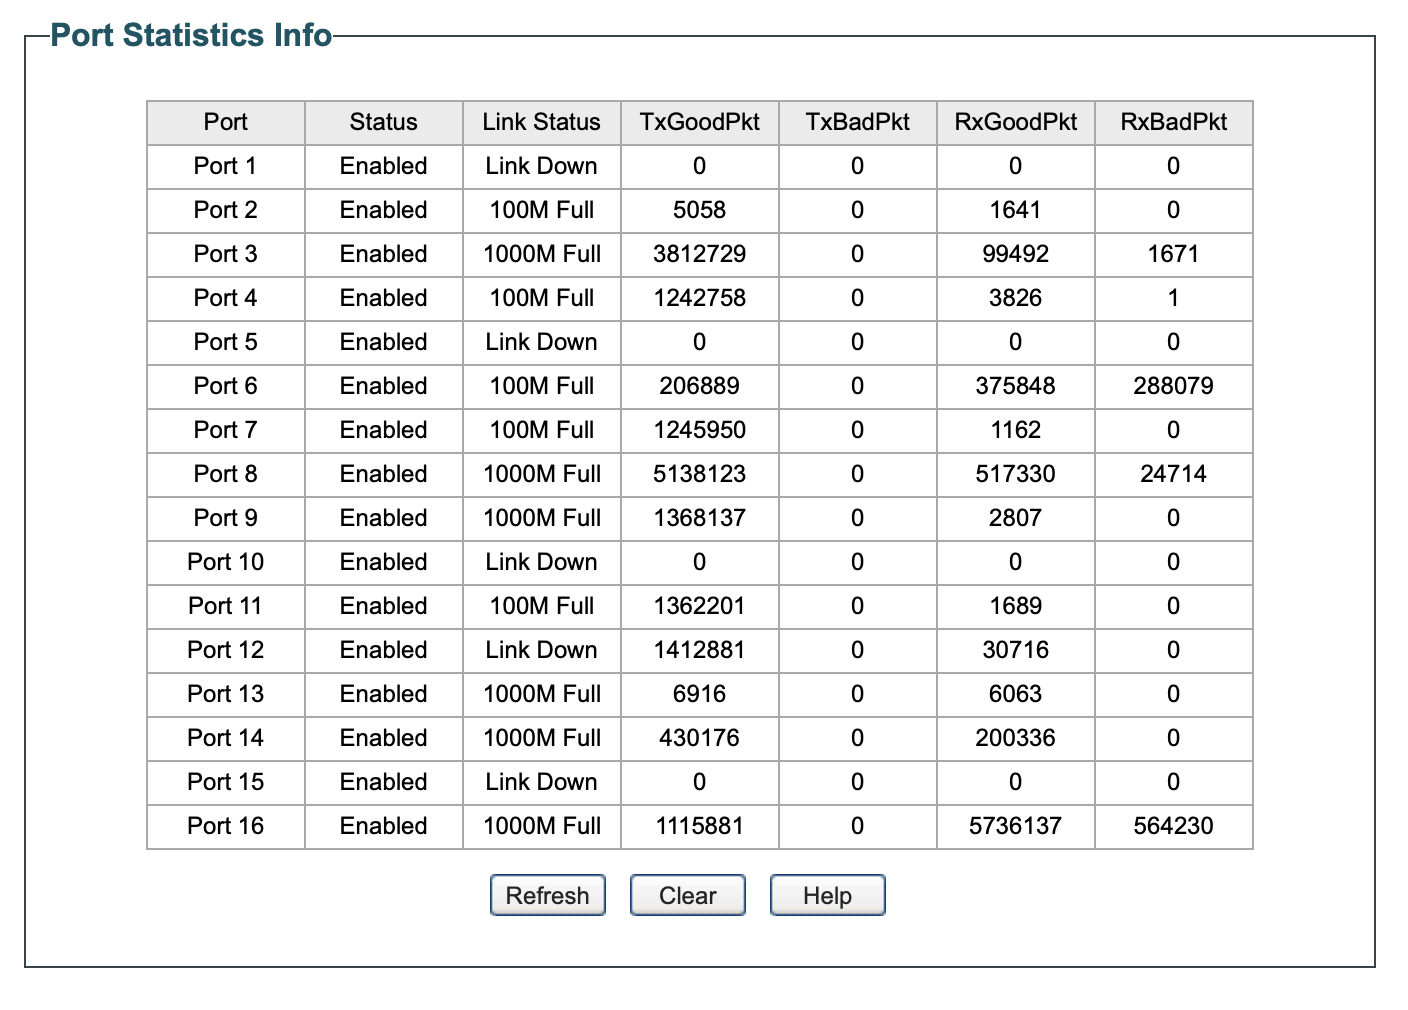
My central switch is a TP-Link TL-SG1016PE. Many VLAN aware devices are connected via tagged/untagged ports. The most important ones are:
- router1 (which is a Mikrotik hEX)
- 2x TP-Link EAP610 access points
- a Netgear GS305E
- Two proxmox nodes
The proxmox nodes have a VLAN aware bridge (the usual vmbr0) and one of the nodes runs router2 as CHR instance. That instance does not have tag= set, i.e., it obtains access to all VLAN interfaces.
After much trial and error, the issue only seems to appear once I enable vrrp3. However, there is nothing special about vrrp3 or vlan3 I am aware of.
I understand that this "super GAU" could in principle happen in a split brain scenario where both router1/router2 think they are master, announce their VRRP addresses and then switch then sees two hosts with the same MAC, panics and shuts down ports. This would explain why it brings down the entire network, including VLANs and hosts that have nothing to do with VRRP.
However, I do not see how this can happen here. Via vrrp98 I make sure that there is only one dedicated network for the VRRP and conntrack exchange.
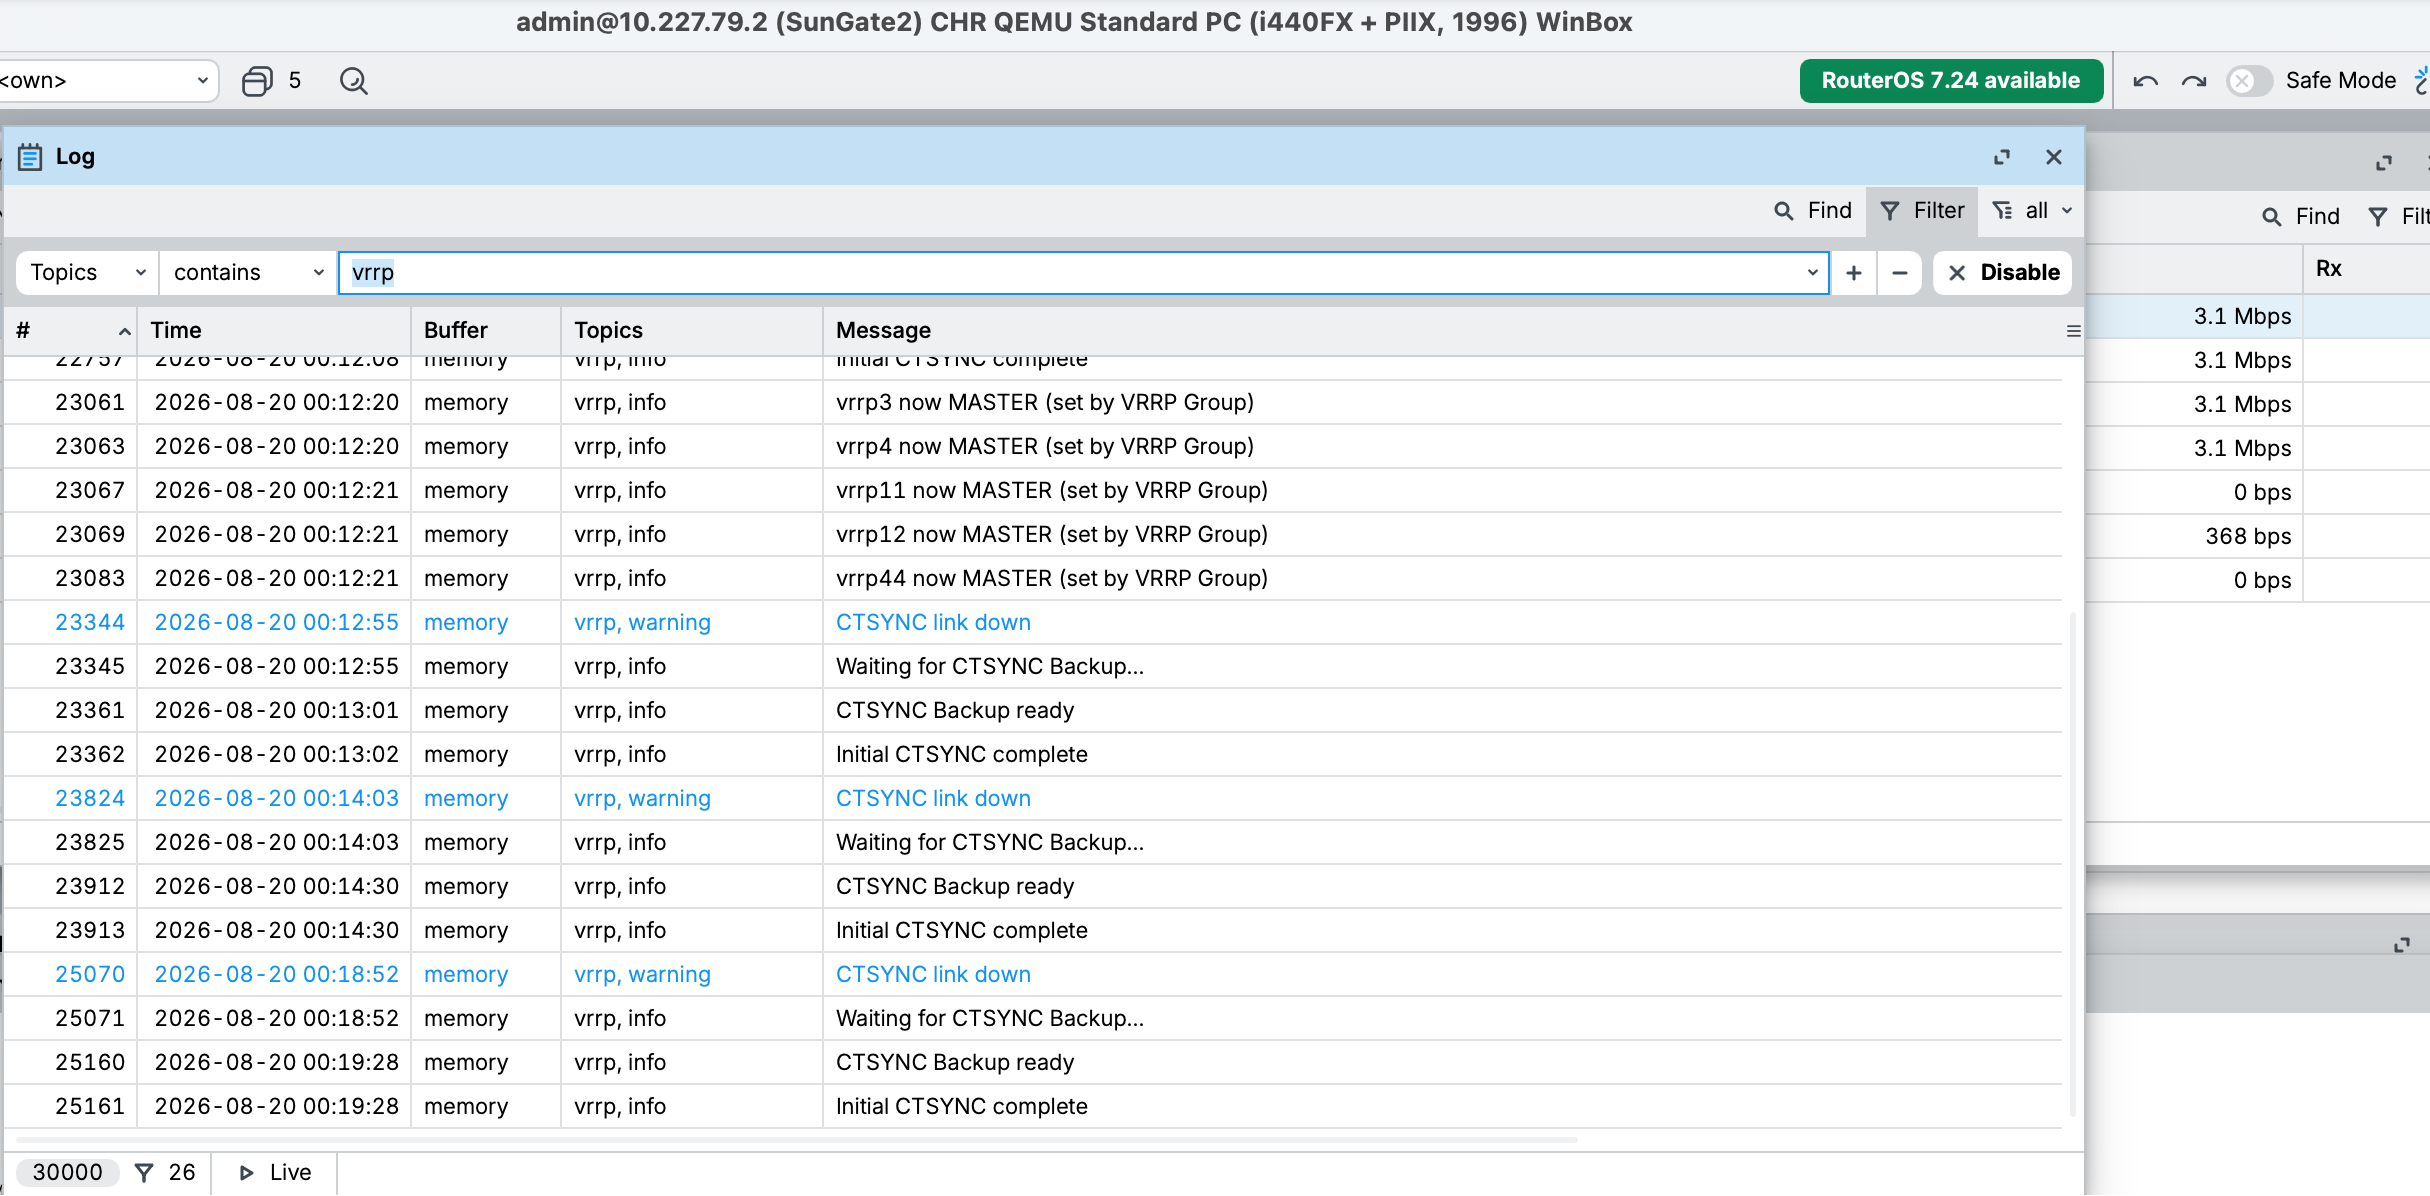
At this point I am just looking for brainstorming of possible ideas what the heck this could cause, what could be special about vlan3 and how to debug further. Note that since I am loosing the whole network it is very hard to check logs in real time or use packet sniffers to see what's going on.
(*) This is despite its interfaces (both vlan and vrrp) being assigned to a VRF. The issue looks similar as identified in countless other VRF related bugs in the past: The traffic goes out in one direction but return traffic is discarded since it's received via an interface which is part of a VRF.