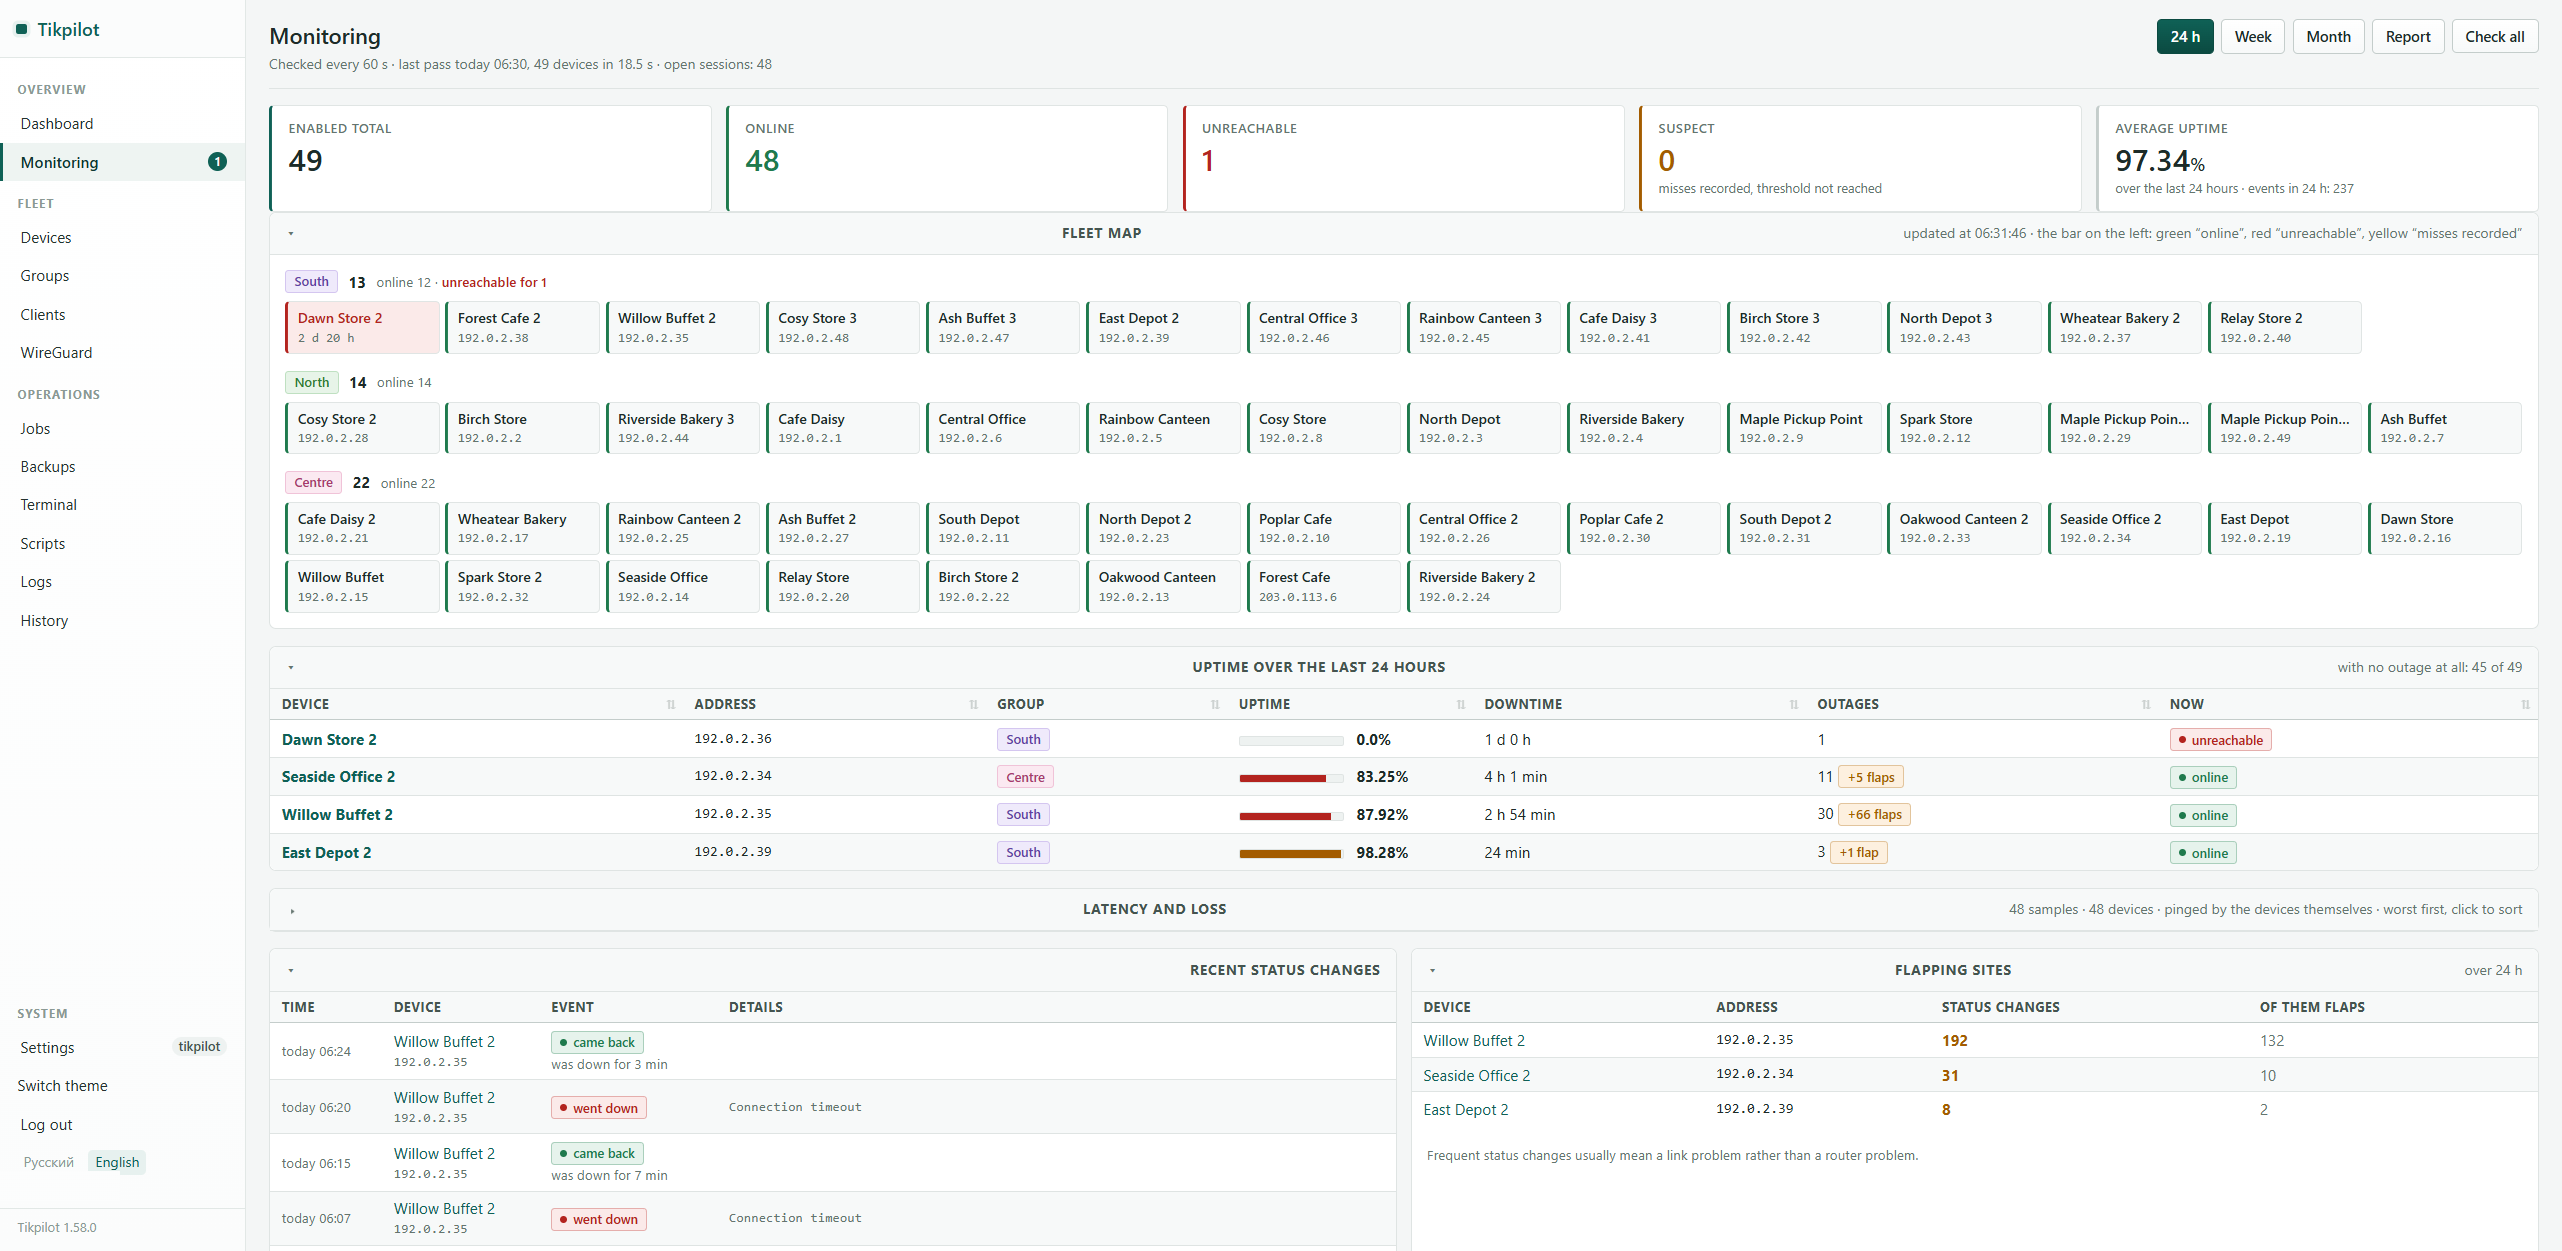
Tikpilot - self-hosted panel for a fleet of MikroTik routers (MIT, no cloud)

I run 49 MikroTik routers across shops, canteens and oilfield sites in
Siberia, reachable over WireGuard with SSTP as a fallback. Doing routine
work on them through WinBox, one window per router, stopped scaling a
while ago. So I built a panel for it and put it on GitHub under MIT.

Site with screenshots and install notes: https://tikpilot.ru

Latest: v1.69.0 (22 Aug) - status is now reachability-first, a
needs-attention list on the dashboard, and speed tests between two of your
own sites. Release notes
What it does

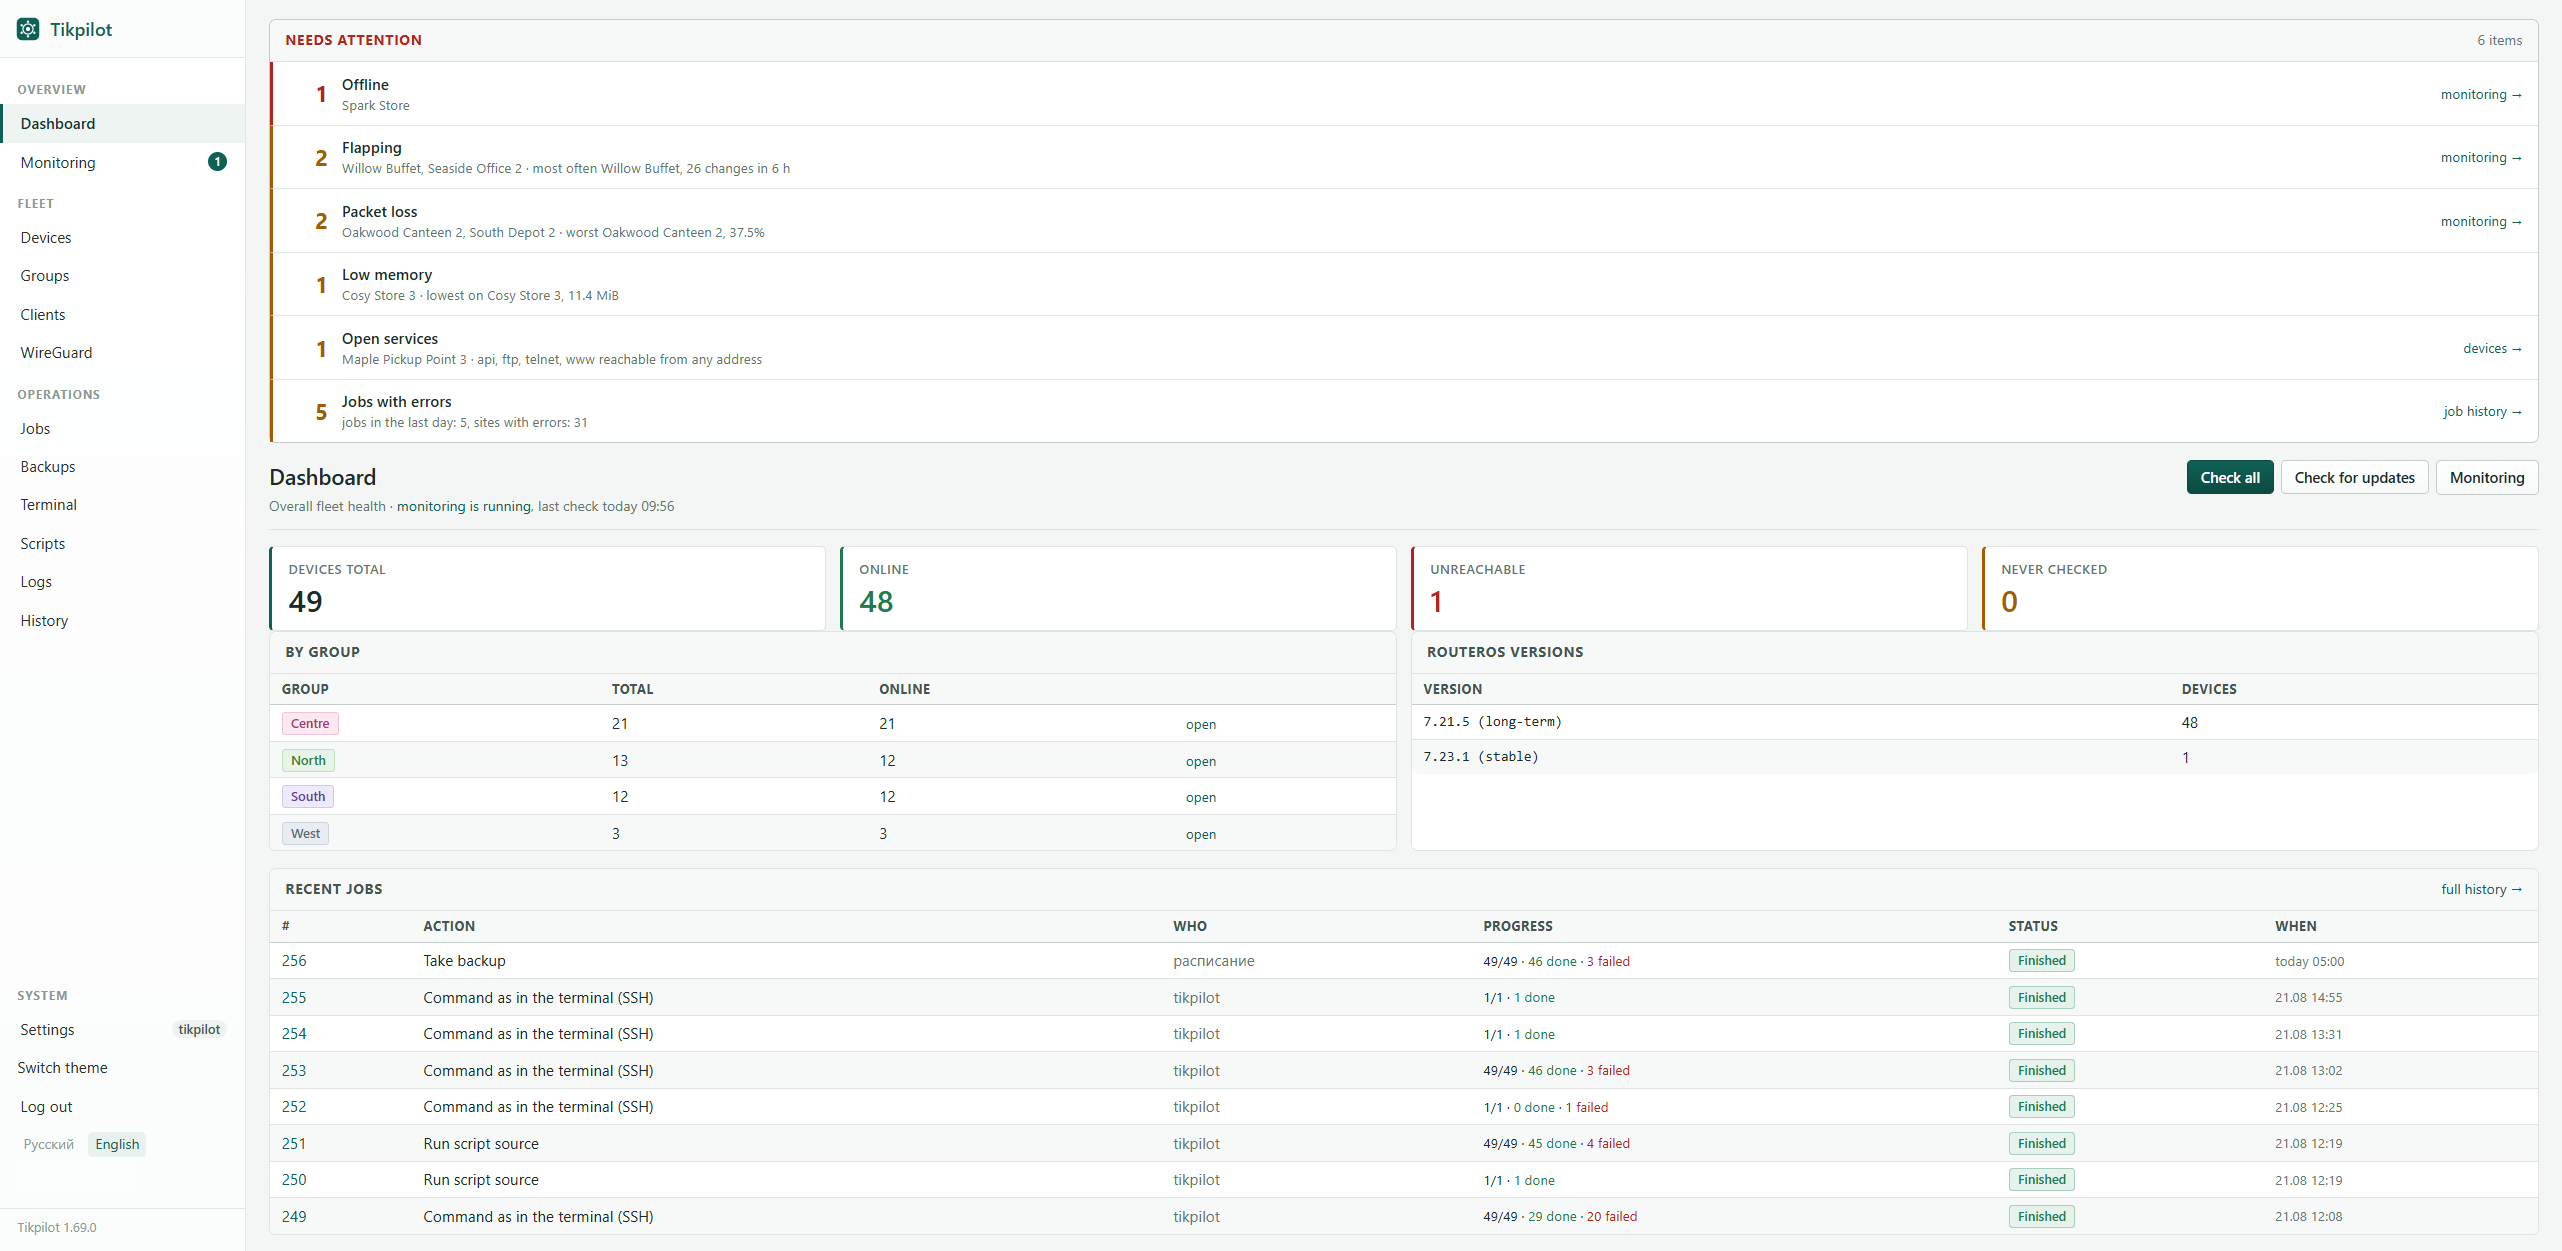
  • Needs attention: one list at the top of the dashboard instead of six
    pages - offline and flapping sites, packet loss, stale backups, syslog
    that stopped arriving, armed rollbacks, failed jobs, CPU and memory
    pressure, services open to any address, available updates. When
    everything is calm the block is not there.
  • One action for the whole fleet: reboot, run a script that is already
    on the router, upload or remove a script, take a backup, set identity,
    check for RouterOS updates, upgrade, measure the bandwidth to another
    site. Every action becomes a job with a per-device result, so you see
    which 3 of 49 failed and why.
  • Availability monitoring: a site counts as up when it answers, over
    the API or over ICMP. If only ICMP answers it stays up and gets a "no
    API" marker, because a broken tunnel is not a dead shop. Uptime per
    site, latency and packet loss measured from the router itself, a fleet
    map and reports by group, device and date range.
  • Backups on a schedule: binary .backup and text .rsc, N copies
    kept per device, diff between any two configs, full-text search across
    all stored configs. Plus an archive of the panel itself, for the day the
    server dies.
  • Script library: keep your scripts in one place and see which router
    actually has which one, without walking the fleet.
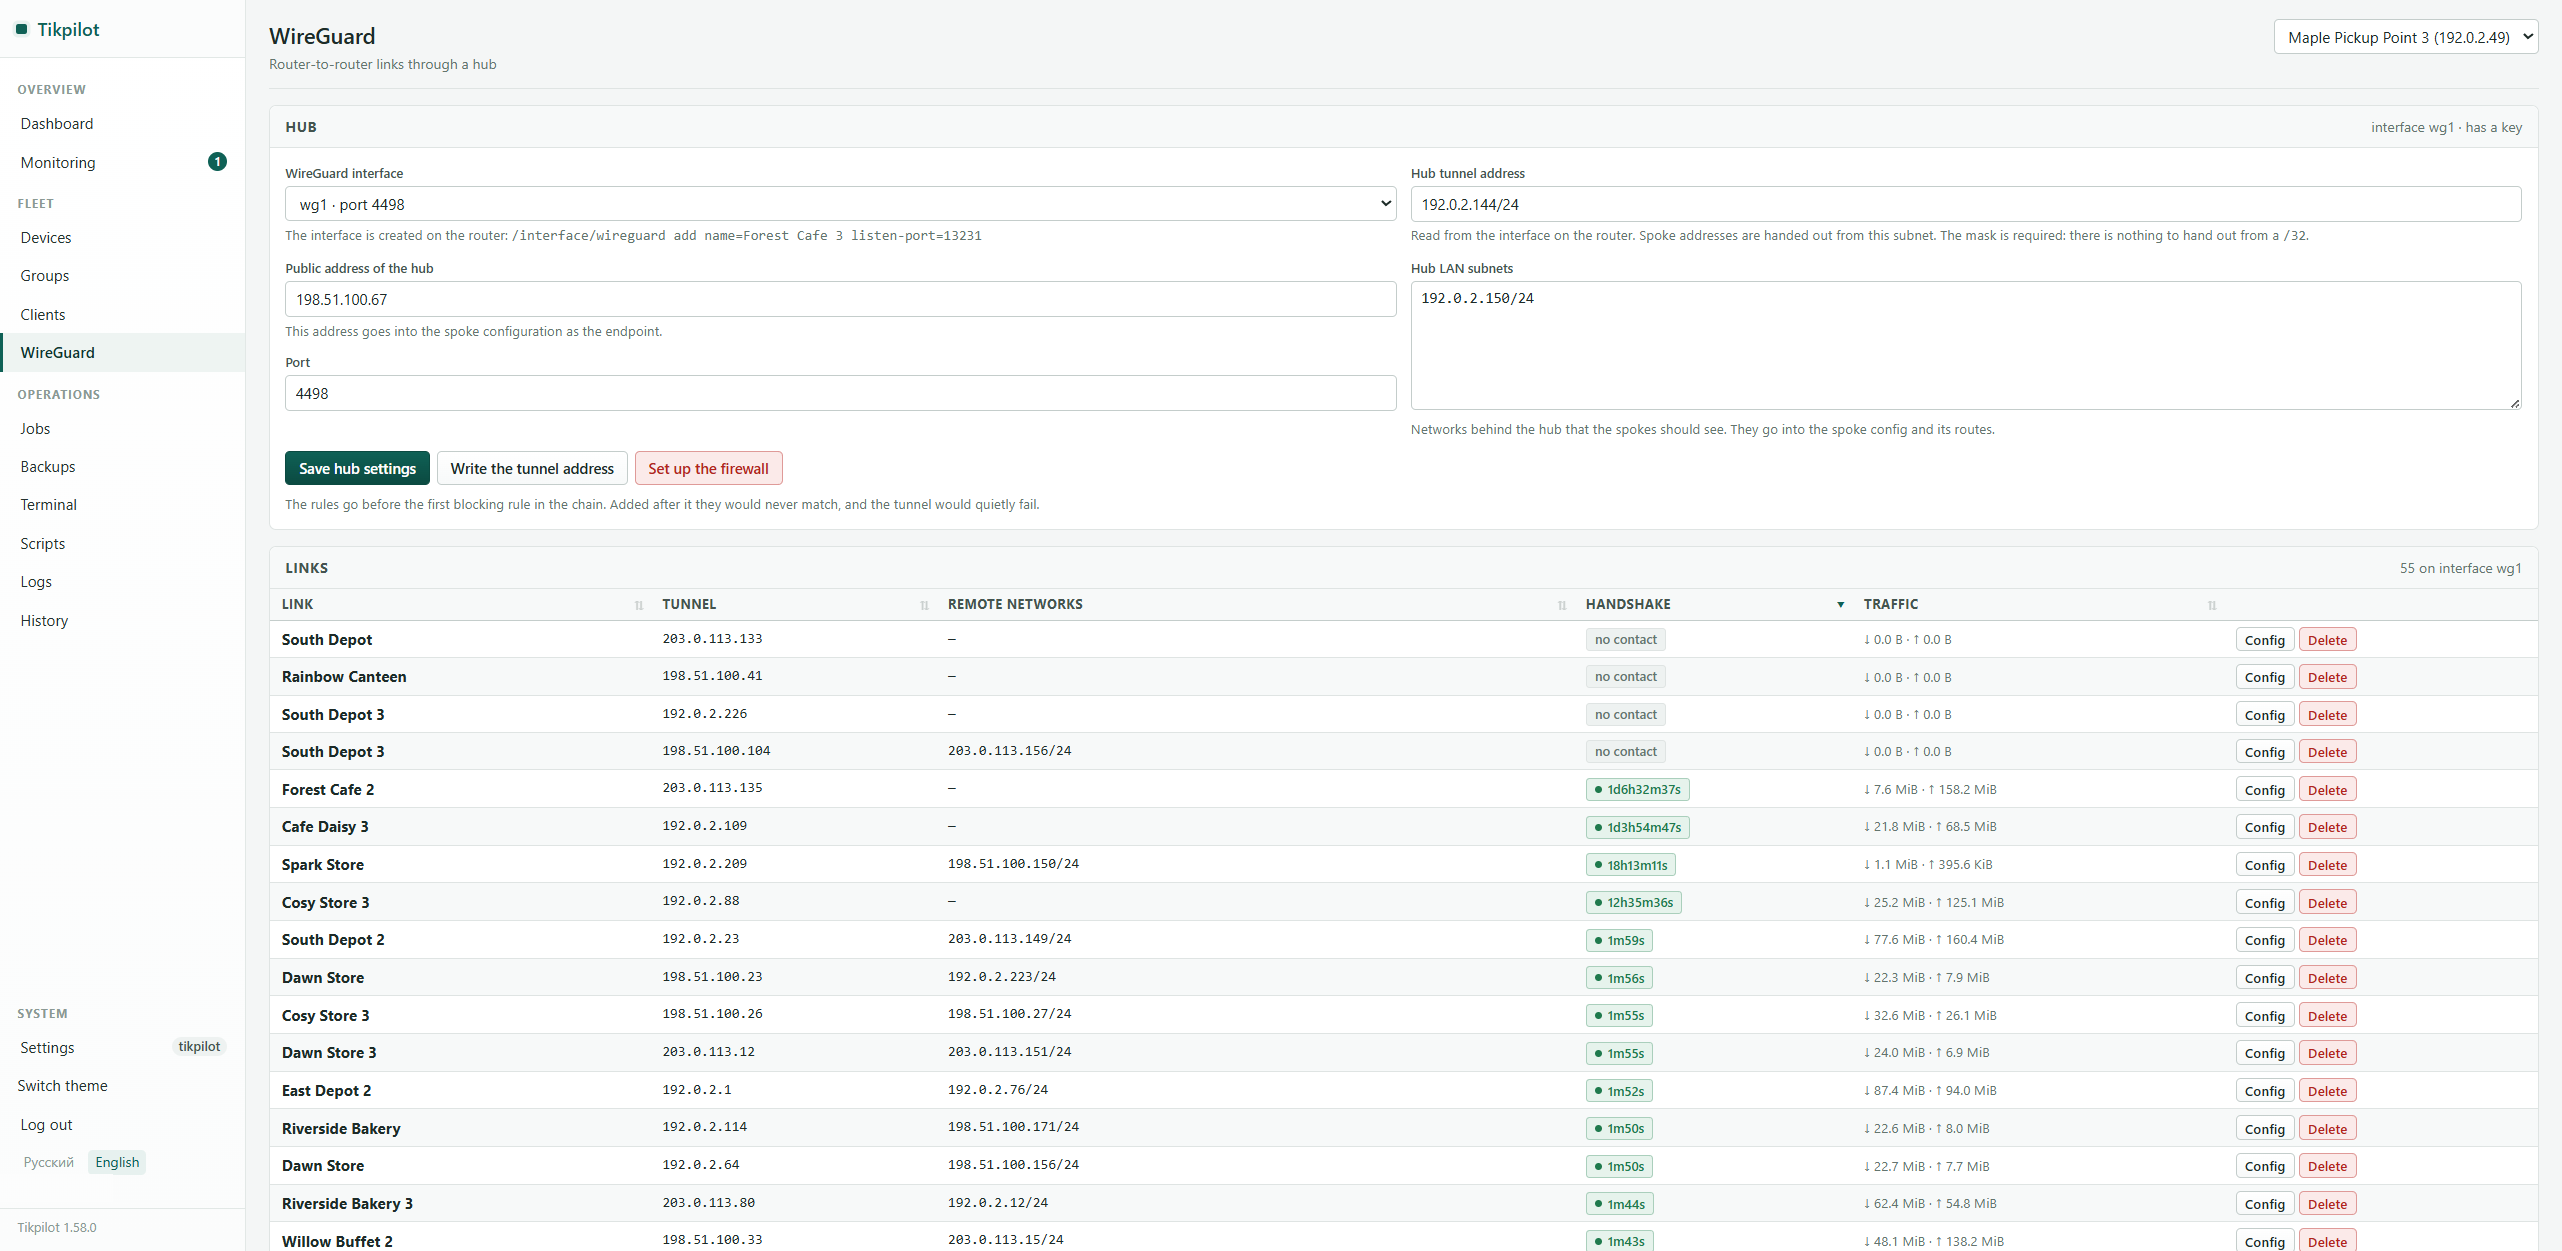
  • WireGuard: router-to-router links through a hub, with handshakes,
    traffic and routes. The spoke config is generated for you.
  • Syslog receiver: logs from the whole fleet with filters and rules for
    hiding the noise.
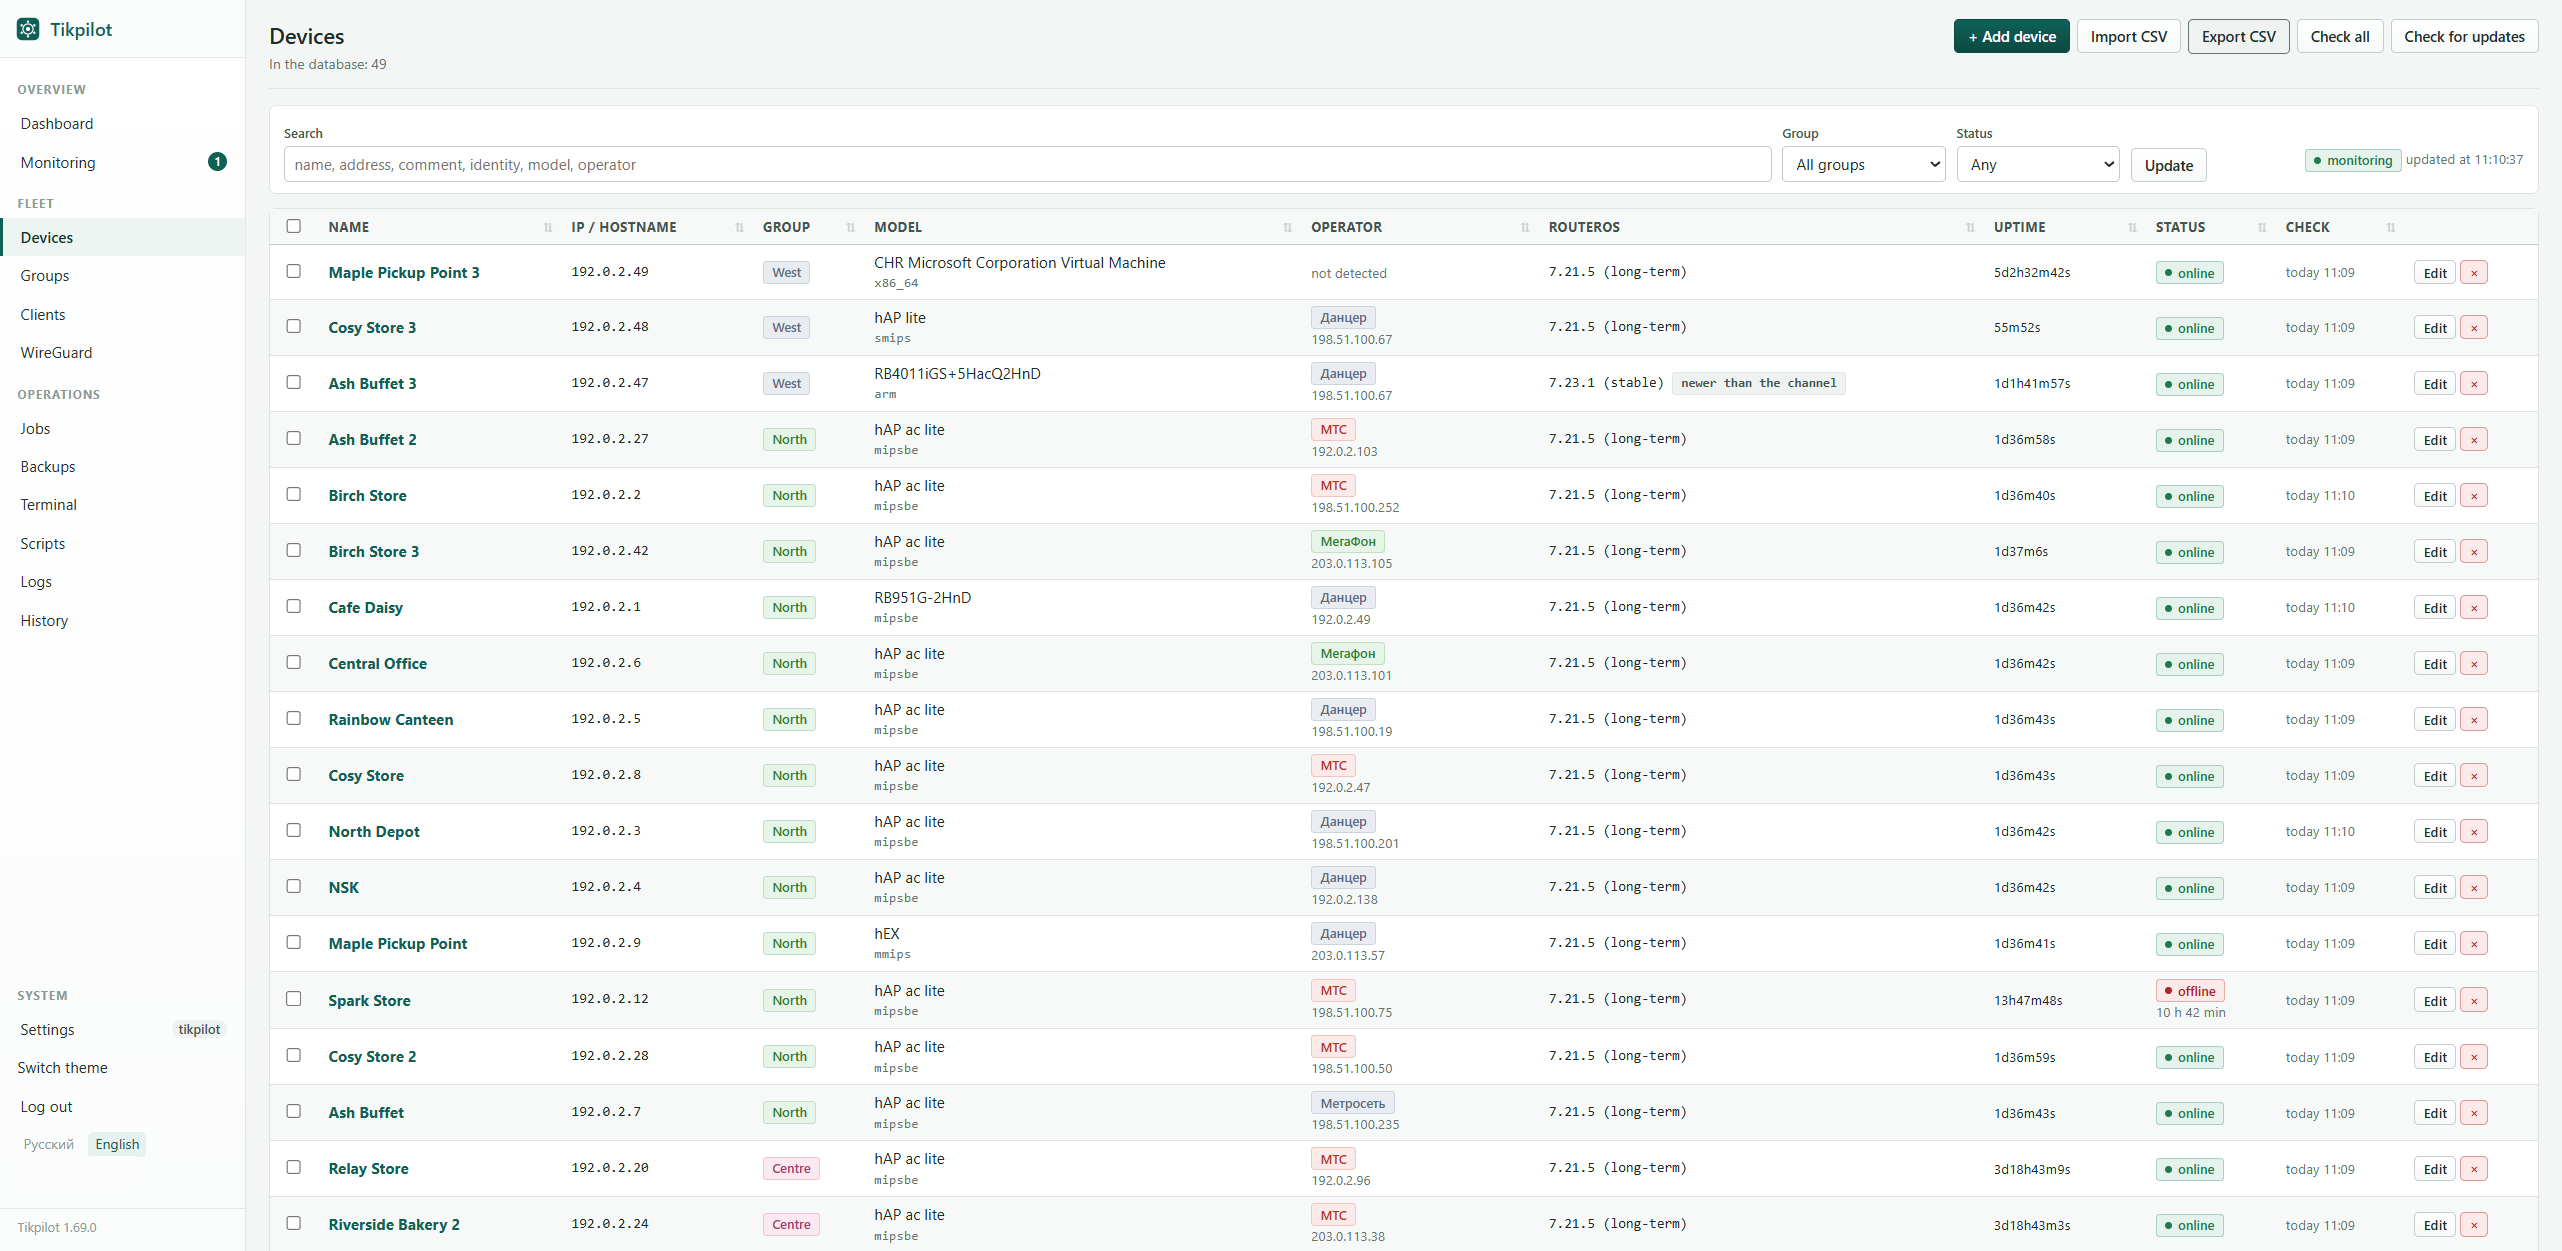
  • Clients behind the routers: what is connected at each site, wired or
    wireless, with vendor by MAC.
  • Users and rights: every capability is granted separately, and an
    account can be limited to certain groups or devices.
  • Interface in English and Russian, switchable from the menu.
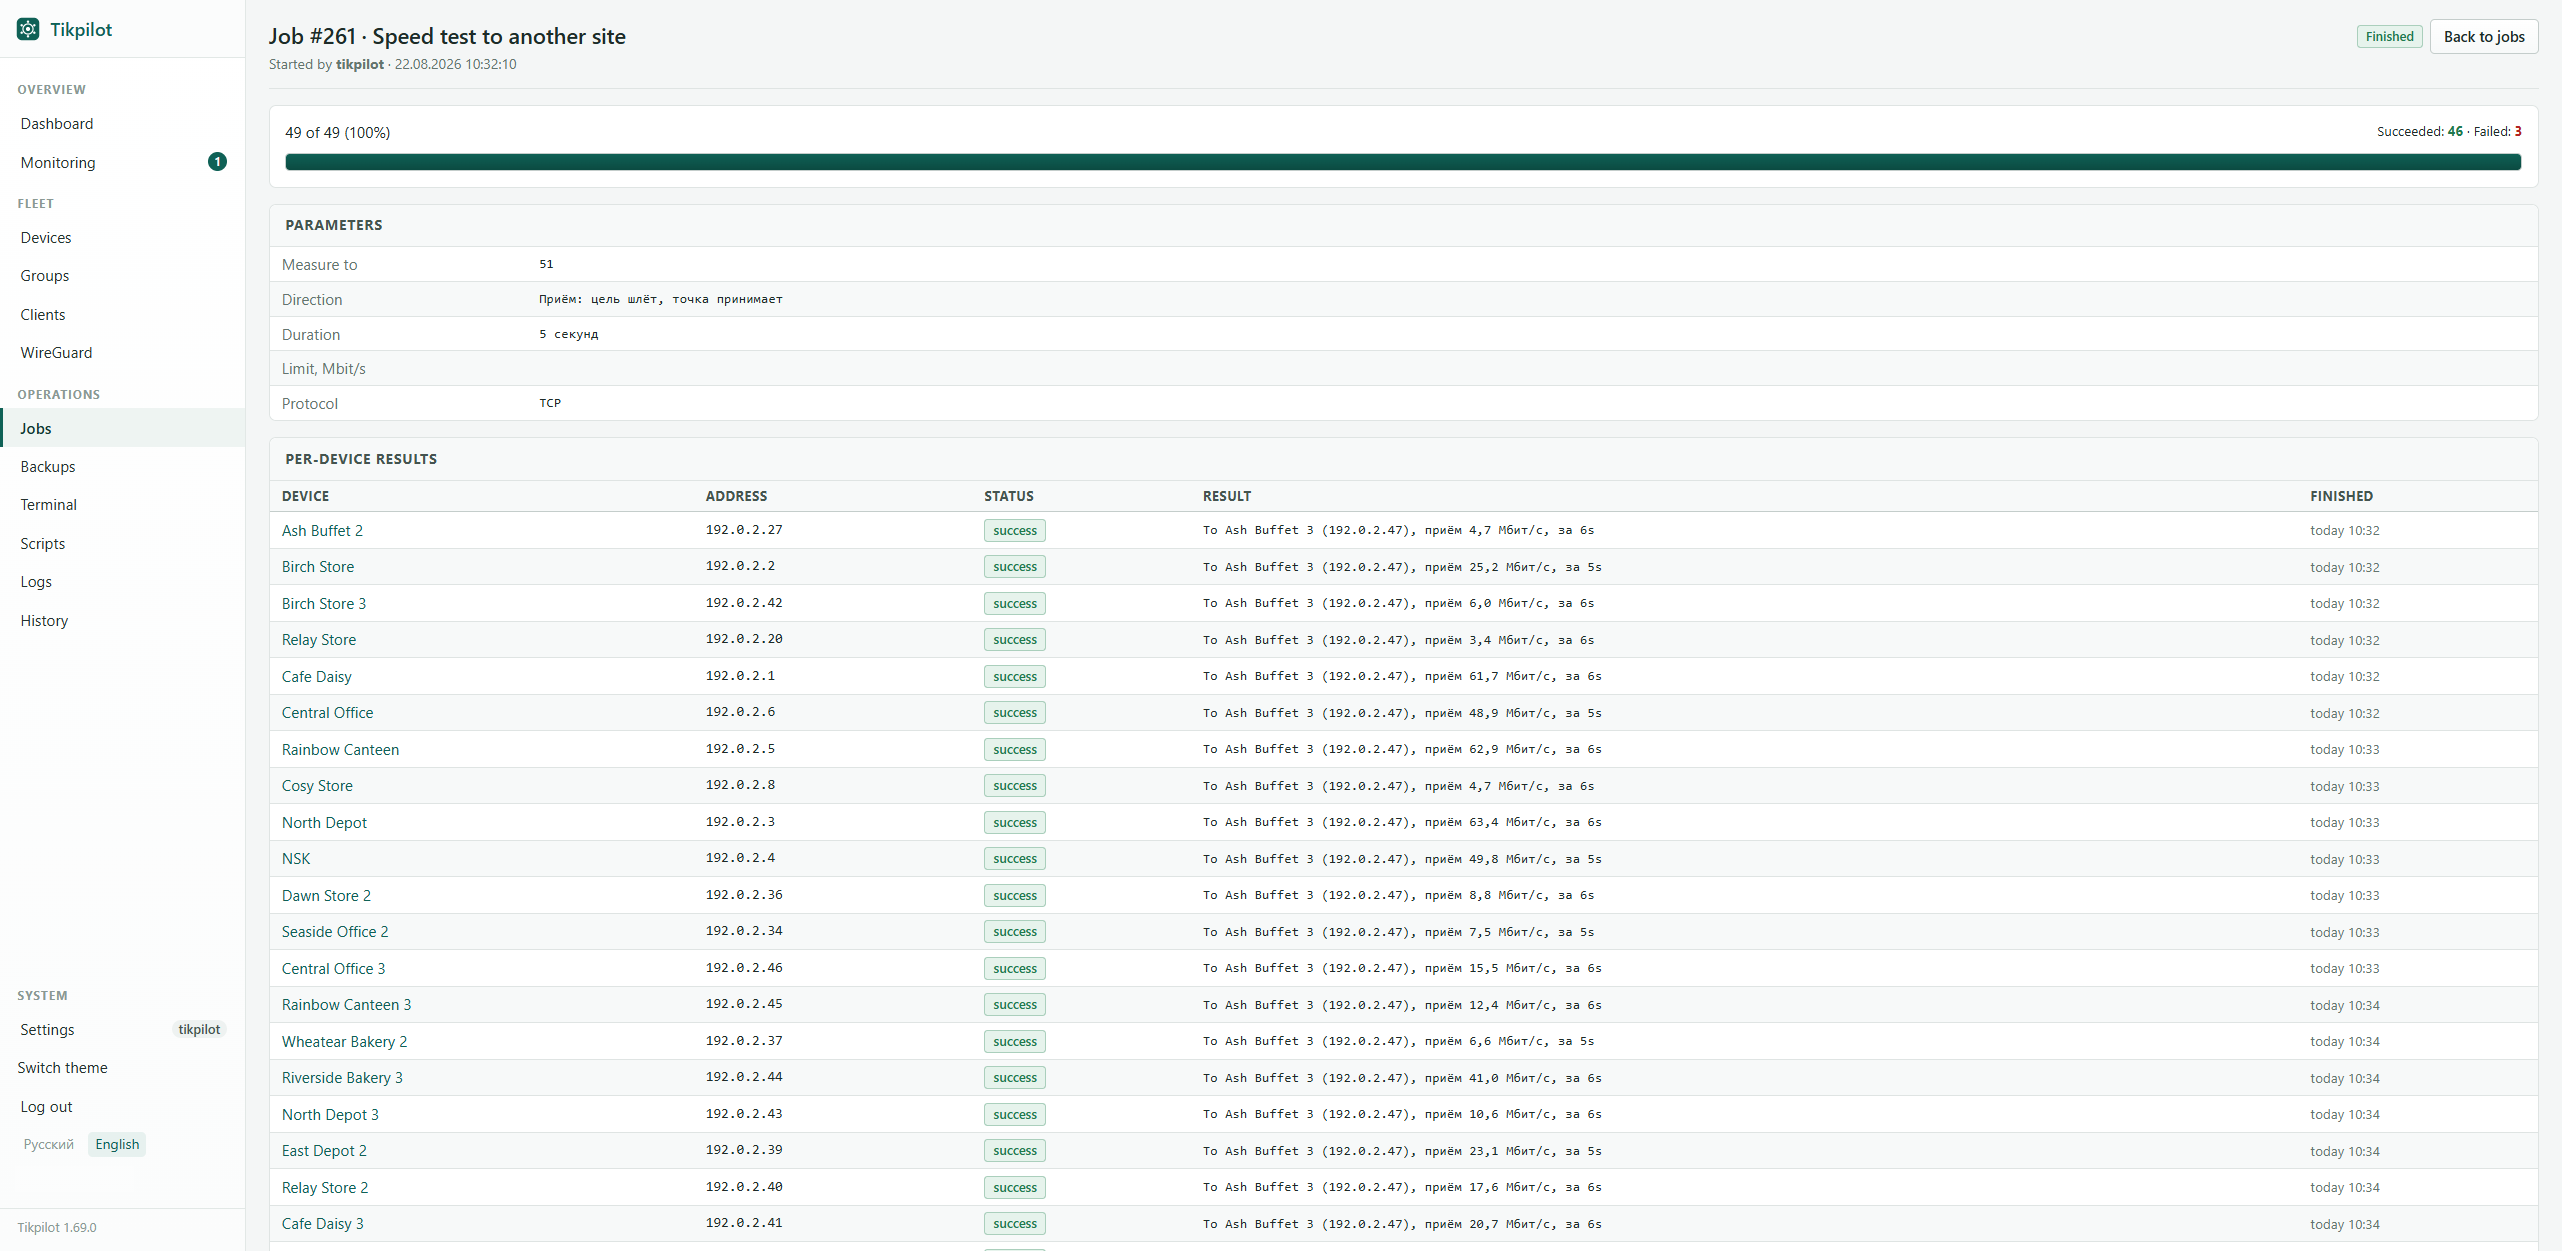
A fleet-wide speed test, one line per site, measured by the routers
themselves rather than from the server:

ВСТАВИТЬ КАРТИНКУ: speedtest.png

What it is not

  • Not an NMS. It does not scan your network, does not draw topology, does
    not poll SNMP. If you need that, you want Zabbix, LibreNMS or The Dude.
  • Not a WinBox replacement. It does the repetitive fleet-wide work; the
    fine tuning still happens in WinBox.
  • Not a cloud service. It runs on your own machine, the data stays in a
    local SQLite file, and nothing is sent anywhere.

Install

git clone https://github.com/maximdr86/tikpilot
cd tikpilot
cp .env.example .env
docker compose up -d

Then open the panel, add devices by hand or import a CSV, and create an
API user on the routers. It talks to RouterOS over the API (8728/8729)
and over SSH for the terminal.

A few details you may care about

  • Router passwords are encrypted at rest with a key kept outside the
    database, and the panel can be limited to trusted networks.
  • Session pooling: the fleet is polled over persistent API sessions, not a
    new login per check, so the routers do not see a login storm.
  • 300+ tests run in CI on Python 3.10, 3.12 and 3.13.
  • There is a screenshot mode: it replaces site names, addresses, client
    names and MACs with made-up ones on the fly, so you can show the panel
    without showing your network. All screenshots above are made with it.

The code was written by Claude, an AI model, under my direction, as a
sysadmin scratching his own itch. It has been running my fleet for weeks,
but I would rather say that up front than have someone find out from the
commit history.

Feedback welcome, especially from anyone running more than a handful of
routers. What would you expect from a tool like this that is missing here?

Hi @maximdr86, welcome to the community, and thanks for sharing this.

Tikpilot solves a problem I know well. Managing even a handful of MikroTik devices through separate Winbox sessions stops scaling quickly, and the further you get from the hardware the worse it gets. A fleet of 49 across oilfield sites in Siberia over WireGuard is a genuinely difficult environment, and the fact that this has been running production there gives the project real credibility that most tools lack.

A few things in the design stand out to me as thoughtful decisions that go beyond the obvious:

The persistent API session approach is correct. Logging in per-check on RouterOS fills the device log within hours at any meaningful poll interval, and the SYN flooding warnings on port 8728 are exactly what you see in practice. Most panels do not solve this.

The separation of download and install in the upgrade flow is something I have wanted in every similar tool. The moment of reboot being unpredictable on a thin link is a real operational problem, and this is the right fix.

The CLAUDE.md mention caught my attention specifically. I am building NexaLink, a multi-tenant ISP management SaaS on Laravel and the MikroTik RouterOS API, and I use Claude with a detailed project context file as well. If you are open to it, would you be willing to share your CLAUDE.md? I am not looking to copy the codebase - the stacks are completely different - but seeing how you structured the project context and guided the AI through a codebase of this complexity would be genuinely valuable. How you defined constraints, described the architecture, and handled iterative refinement across sessions is what I am curious about.

Either way, starred and watching. Good work.

Thanks for the detailed read, and good luck with NexaLink.

Happy to share it. I have just put an English version of the project
context in the repo:

What mattered, in short:

  • Most of it is not a feature list. It describes the environment: bad and
    expensive links, one admin, a site visit costs a day and real money.
    Almost every design decision falls out of that, and the model makes far
    better calls when it knows why rather than what.
  • A separate appendix of RouterOS gotchas collected from production, not
    from documentation: /interface/lte/monitor needing numbers=,
    MultiTrapError not being a subclass of TrapError, /ip service with an
    address list accepting the TCP connection and then resetting it. That
    appendix saved more time than anything else in the file.
  • Hard rules that never move: no external CDN, no build step, tests after
    every stage, and "ask me about anything ambiguous before you start".
  • One stage at a time, each ending with a working panel and a green test
    suite. Long sessions drift; short ones with tests do not.

For continuity across sessions the changelog does the work: every version
records what changed and why, so the reasoning is recoverable later without
carrying it in context.

The two things you singled out both came from getting burned rather than
from planning. Persistent sessions after watching a router log fill with
logins, and splitting download from install after an upgrade started over a
satellite link at the wrong moment.

what's the location of those oilfield sites (asking for a friend)

Western Siberia, somewhere between the mosquitoes and the nearest paved
road. That is about as precise as I get in public, which is also why the
panel has a screenshot mode

Yet another A.I. slop codebase that will be publicly abandoned in less than a year. :yawning_face:

Might well be. I built it for my own fleet and I will keep it going while it is useful to me. It is MIT, so if I stop and someone still needs it, nothing is in their way.

Small update for anyone following the thread: v1.62.0 is out, and it adds
the part that was missing.

Thresholds. A rule is a metric, a comparison, a value and a hold time.
The hold is the point: a spike of CPU during a nightly backup is not an
event, half an hour at the same level is. It measures what the panel
already collects anyway - how long a site has been unreachable, CPU load,
free memory, temperature, latency, packet loss, interface throughput and
the age of the last backup. Scope per rule: the whole fleet, a group or a
single site. A value that cannot be read counts as neither an alert nor a
recovery, so a board with no temperature sensor simply stays quiet.

Notifications in Telegram, as a digest. Everything that piled up goes
out in one message every N minutes, with quiet hours and a pause per rule
and site. Fifteen outages are fifteen lines, not fifteen messages, which
is the only way I have seen alerting survive on a fleet with flapping
links. Off until you turn it on: the panel promises to work in a network
with no internet. When it stays silent it now says why - sending is off,
quiet hours, the digest interval has not passed, no chat is set up, or
there is nothing to send. The bot token is stored encrypted with the same
key as the router passwords.

Liveness signal. The panel cannot report its own death, so it does the
opposite: every few minutes it pings an address you set, and whoever stops
receiving the ping raises the alarm. healthchecks.io, a cron job on
another machine, anything that can wait for a request.

Interface throughput. Computed from the byte counters read on two
polls rather than /interface/monitor-traffic: an average over the
interval instead of a one second spike, and one command for every
interface instead of one per interface. The uplink is detected from the
default route, immediate-gw in RouterOS 7 and gateway-status in
version 6. A counter that went backwards is skipped rather than turned
into a spike of gigabits, since a reboot, a recreated interface and a
32 bit counter wrapping all look the same.

337 tests in CI on Python 3.10, 3.12 and 3.13. Upgrading is git pull and
docker compose up -d --build, the database migrates itself.

v1.69.0 is out. Two of the changes came from being wrong about my own
fleet, so I will lead with those rather than with the feature list.

A site being unreachable and our API being unreachable are not the same
thing.
Sites kept sitting in the panel as offline while WinBox opened
them fine. The panel was not lying, it really could not connect on 8728,
but it was answering a question nobody asked. What the person looking at
the dashboard wants to know first is whether the shop is alive; whether
the panel can manage it is the second question.

So the status is now reachability first: online means the router answers,
a ping being enough. If ICMP answers and the API does not, the site stays
online and gets a "no API" marker instead - a link, a tunnel or the
service on the router, and nobody has to drive out. Offline means both are
silent. Downtime and availability percentages follow the same rule, which
also stopped the 30-minute unreachable rule from waking me up over a
choked link.

Only devices that failed over the API get pinged, so on a normal day that
is nobody. It goes through the system ping with no root, and if there is
no ping in the container the API decides alone, as before.

Not connected: No existing session - if you have run a command
across a whole fleet over SSH, you have seen this one. I spent a while
looking at the wrong end of it. It is not authentication and not the
router refusing anything: the TCP connection is established and the SSH
handshake does not finish inside the client timeout. Weak board, lossy
link, and a dozen parallel sessions arriving at once make it reliable.
In my case 22 of 49 sites failed a bulk command with it. The panel now
says that in words instead of showing the raw string, and the SSH timeout
is a setting rather than a hardcoded ten seconds.

Related, and the reason I hit it: bulk actions run in parallel. That is
right for a reboot and wrong for anything that measures, which brings me
to the two new features.

Needs attention. The panel was good at "how are things" and bad at
"what should I deal with". The second answer was spread over six pages, so
now there is one list at the top of the dashboard: offline and flapping
sites, packet loss measured by the routers themselves, backups older than
a week, syslog that used to arrive and stopped, armed rollbacks, jobs with
errors, CPU and memory pressure, the panel's own disk filling up, services
open to any address, available RouterOS updates. Nothing extra is polled
for it - every check runs over data that was already collected. When
everything is calm the block is not rendered at all.

Speed test between two of your own sites. The panel has credentials
for both ends, so it enables the btest server on the target, supplies the
target's own login, runs /tool/bandwidth-test from the source site and
switches the server back off afterwards, including when the test failed.
Direction, duration, protocol and a cap are configurable.

The first fleet-wide run taught me the thing I mentioned above: twelve
sites measuring towards one target at the same time split that target's
channel between them, and I got twelve understated numbers that each
looked like a measurement. Measuring actions now go one site at a time.

The rest since 1.62, briefly: the panel watches its own free disk after
running out of it and taking itself down; the syslog receiver survives a
device deleted mid-batch, which used to kill the writer thread silently
for a whole day; settings are five tabs with their own URLs; Add to Home
Screen gives a usable app on a phone, terminal included; charts got
gridlines, a marked peak and hover values; and there is a per-interface
total of how much went through over a day or a week.

Full notes: Releases · maximdr86/tikpilot · GitHub

Upgrading is git pull && docker compose up -d --build, the database
migrates itself. 365 tests plus 12 slow ones on Python 3.10, 3.12 and
3.13.